Tags
Share
TypeSafe AI’s Jev is built for a different kind of AI work: making defined decisions rather than generating content. We’re testing what that could mean for agentic software development and Exadel Colleague.
The small decisions around every agent step
We think of an AI coding agent in terms of what it generates. And for good reason: it writes code, proposes changes, and produces new artifacts. But in reality, much of the work inside an agentic workflow has nothing to do with generation at all.
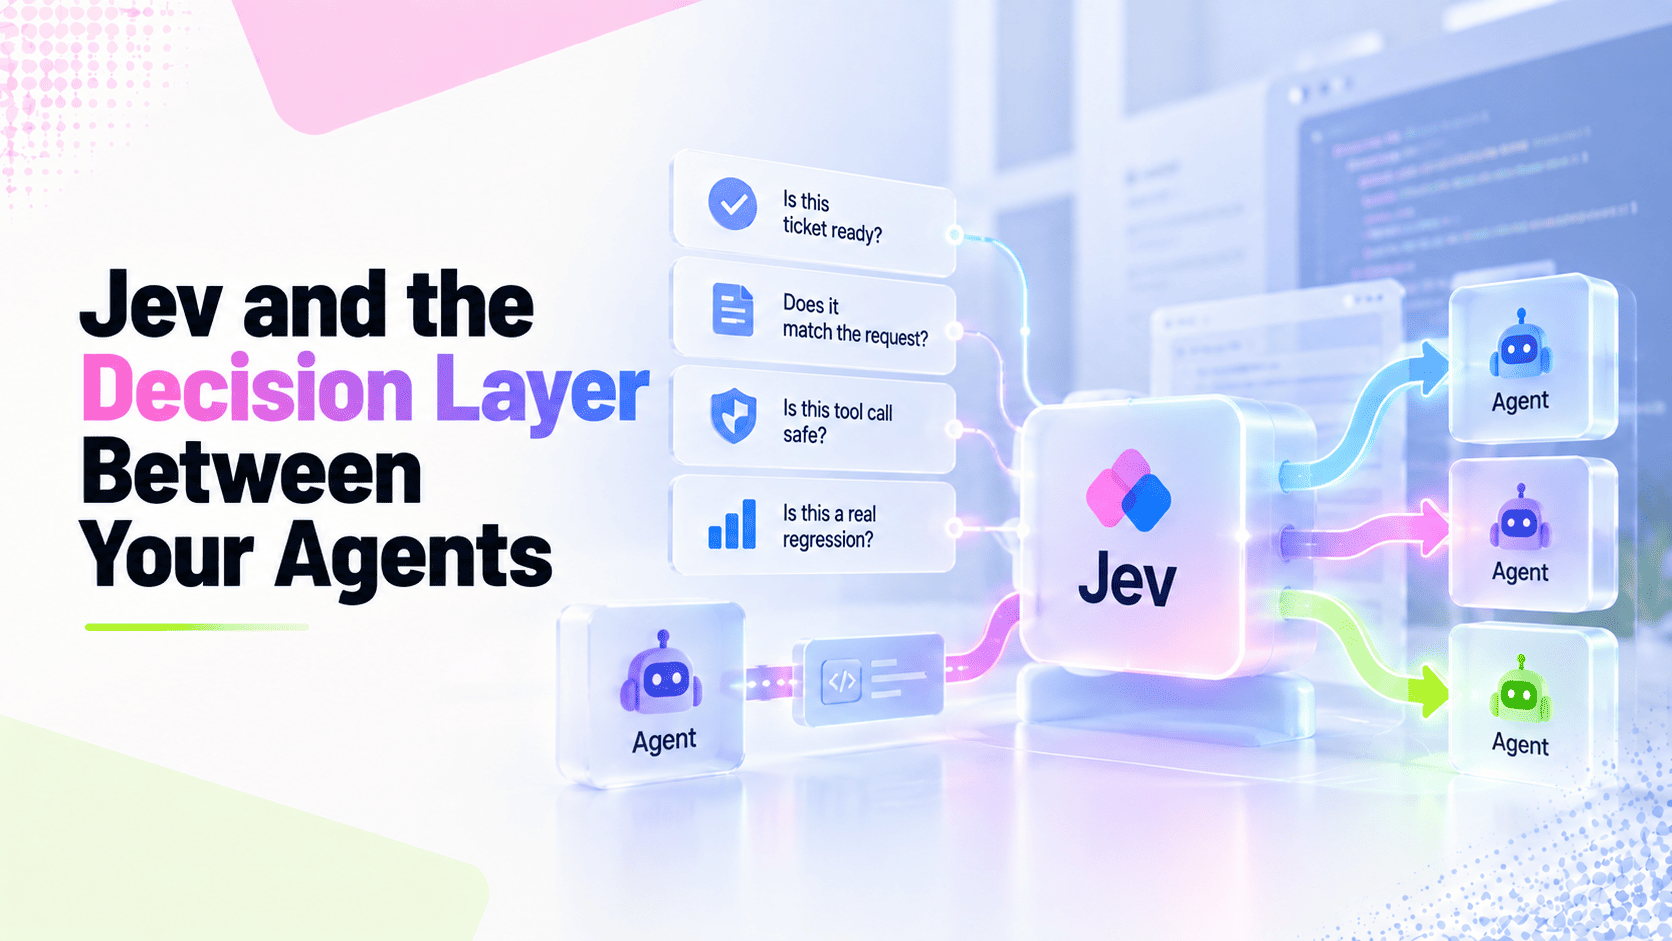
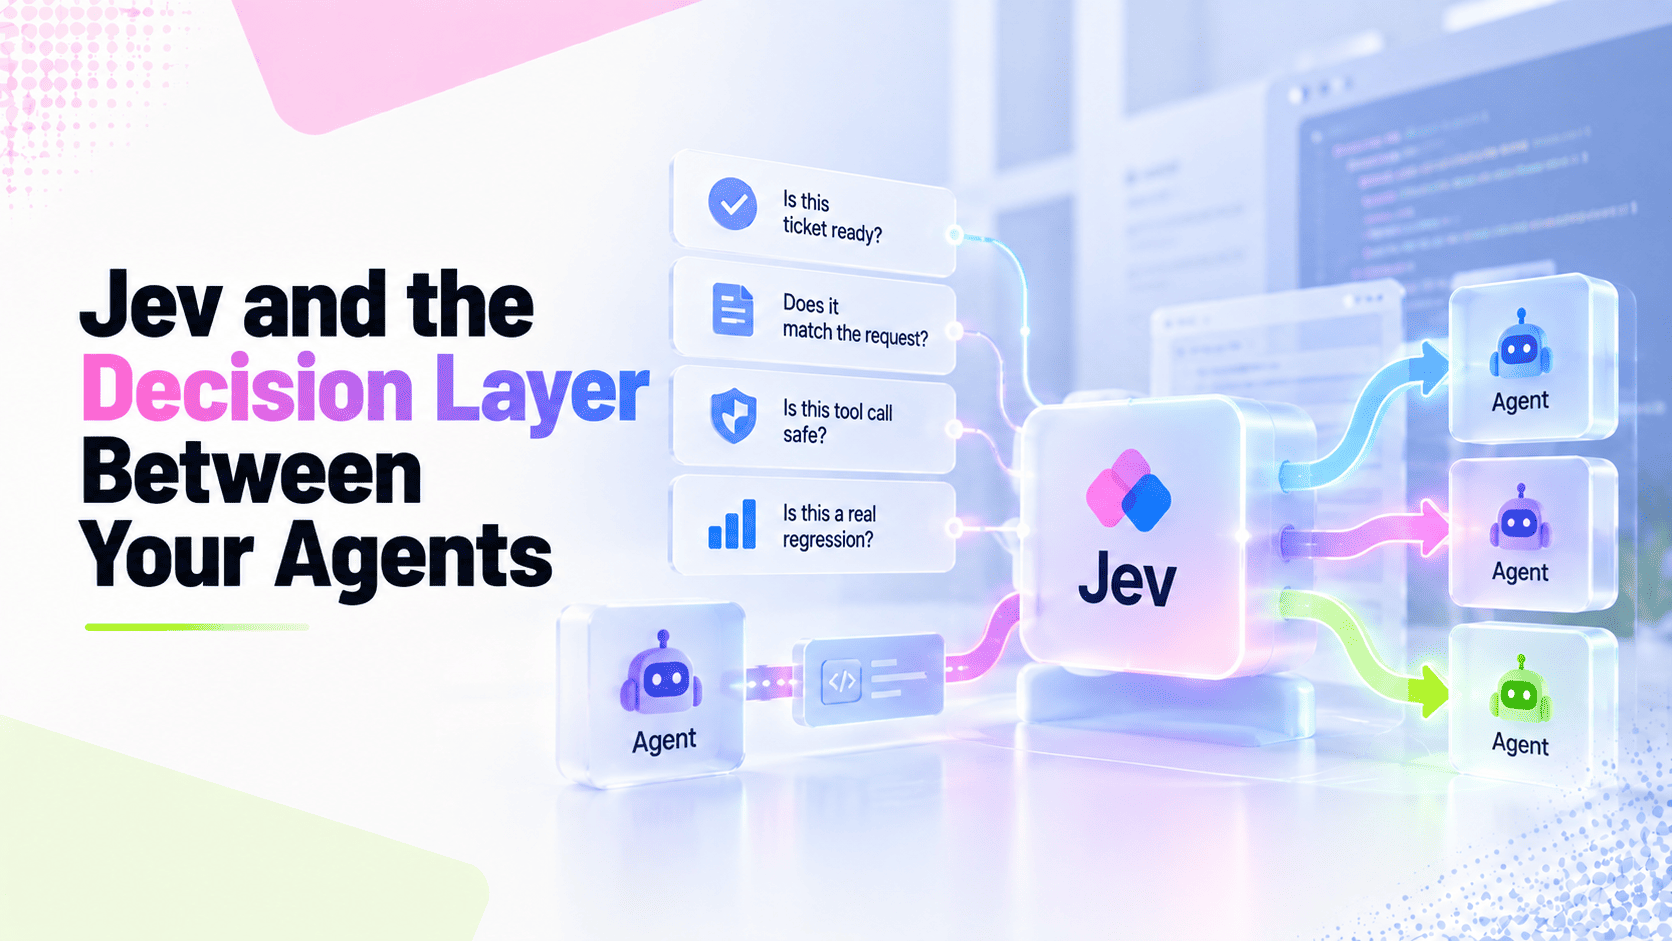
Around every step that generates anything, ‘smaller’ but crucial decisions need to be made: Is this ticket ready to work on? Does this change match what was asked? Is this tool call safe? Is this test failure a real regression? Which files are relevant enough to put into context?
Today, the same powerful, general-purpose AI models used for generation also make many of these decisions. They read the ticket, code, test result, or tool request and make the call. But that comes at a cost. Even a small decision requires a model designed for far more complex work to process the input and generate an answer. That takes time and consumes tokens. And while the model can tell you how confident it is, that confidence isn’t a reliable probability.
Jev, launched by TypeSafe AI in September 2026, takes a different approach. So what exactly is Jev? TypeSafe describes Jev as a System One model: a model designed to answer narrowly defined questions rather than generate content. This creates an interesting new possibility for agentic software development: separating generation from the decisions surrounding it.
Why frontier models make small decisions today—and what that costs
Frontier models make many of these decisions today for a simple reason: they can interpret the ticket, code diff, test result, or tool request well enough to make the call.
The problem becomes clearer when you look at how often these decisions happen. One generation call can be surrounded by many smaller calls. Should this action proceed? Is this file relevant? Did the change satisfy the requirement? Should the agent retry or stop? Does this result need human review? Each time a generative model makes one of those decisions, it has to process the input and generate an answer. That takes time and consumes tokens. Now multiply that across an autonomous agent run and the cost of all those small decisions starts to add up. So don’t just count generation calls. Count the decisions around them too.
Jev is designed specifically for that narrower class of work.
What is a System One model?
A System One model is designed to answer narrowly defined questions rather than generate content. Jev is TypeSafe AI’s System One model. In an agent pipeline, Jev could sit between generative steps and make smaller decisions about what happens next, using defined answers and confidence scores that software can act on directly.
It doesn’t behave like a smaller version of a language model. In fact, Jev writes nothing at all. You give Jev a state, such as a ticket, diff, or message, together with a set of typed questions. Jev returns a typed answer for each question, together with probabilities that indicate its confidence. TypeSafe currently provides three question types. Choice selects one answer from a set of options you define. Score places the input somewhere on a scale whose levels you specify. Noul answers a yes/no question and returns the probability of yes.
According to TypeSafe, Jev can answer several questions about the same input at once. Asking ten questions therefore takes barely more time than asking one. Software can read the result and act on it directly, without requiring a person to interpret it.
That changes what a confidence score can do. Suppose an action can proceed automatically above one threshold, require another check above a lower threshold, and be escalated to an engineer below that. Different actions can use different thresholds because the consequences of getting them wrong are different. A read-only operation doesn’t need to carry the same threshold as a database schema migration. In that sense, confidence becomes part of the hand-off contract between one step in the system and the next.
According to TypeSafe, Jev costs $0.042 per million input tokens, with free output, and responds in 70 to 500 milliseconds. The current context limit is 64k per request, with 32k available for the state plus the longest question. These are TypeSafe's published figures as of September 2026.

Your AI Partner
Explore where decision gates could fit in your agent pipeline.
Why we are testing Jev in agentic delivery and Exadel Colleague
This separation between generation and decision-making is why we’re testing Jev in our agentic software development work and in Exadel Colleague. Jev wasn’t designed to replace the generative models doing software engineering work. We want to find out where a specialized decision model could sit between those generative steps.
Our AI-enabled product engineering work gives us plenty of opportunities to test that. Every agent run involves repeated decisions about what to generate, what to test, what to review, which tools to use, and when to hand work off.
We don’t have Exadel performance data or savings numbers to publish yet. We’ll publish them when we do.
Where Jev could sit in a delivery pipeline
The following Jev use cases show where it could fit in a delivery pipeline and the kinds of decisions it could take on.
A risk gate for AI agent tool calls
An autonomous agent needs different permissions for different actions. Before an agent takes an action, Jev could classify the risk and check whether the action can be reversed. The system could then apply a confidence threshold based on what’s at stake. For example, reading a file might proceed at modest confidence. A schema migration might always require a person. Instead of asking a model whether an action simply “looks safe,” the system could ask Jev a set of defined questions. The answers would determine what happens next. That gives security teams a clearer basis for deciding which actions an autonomous agent can take.
Choosing what goes into the context
More context doesn’t automatically produce a better agent. In a large repository, an agent may have hundreds of potentially relevant files but limited space for the information that actually matters. Jev could score each candidate file for relevance to the current task. The system would then select the highest-scoring files before the generative model begins its work. This makes context selection itself a decision layer.
Jev has its own context limits. Its current state limit is 32k, so a large repository won’t fit. Deciding what information reaches the model remains an engineering problem. That also makes context selection an interesting potential use for a specialized decision model.
Confidence as the hand-off signal
A reviewer learns little from a queue of agent-generated changes all marked “ready.” A confidence score can make that hand-off much more useful. For example, the system might report high confidence that a change matches the ticket requirements but lower confidence that it covers the relevant edge cases. This gives the reviewer a stronger signal about where their judgment is needed.
Confidence can also determine what the system does next. High confidence might allow the agent to continue. Lower confidence might trigger another check or send the decision to a person. The threshold can change depending on what’s at stake if the answer is wrong.
Is this ticket ready for an agent?
Before an agent starts work, Jev could check whether the ticket gives it enough to go on. Are the acceptance criteria checkable? Does the ticket identify the part of the codebase involved? The answers could determine whether the agent starts work at all. If the ticket isn’t ready, the system can flag it before the agent spends time producing a change that an engineer later rejects.
Real regression or flaky test?
A failed test leaves an agent with another decision to make. Is there a real problem with the code? Is the test itself unreliable? Is the environment causing the failure? Or does the test need updating?
The answer will determine what happens next. The agent might try again, change the code, or stop and ask for help. Get that decision wrong and the agent could keep trying to fix the wrong problem, wasting time and budget in the process. Jev could identify the likely cause of the failure. The software would then use that answer, and Jev’s confidence in it, to decide what happens next.
What Jev costs and where the saving comes from
Jev doesn’t make generation cheaper. Its impact on agentic software development cost comes from using it for the smaller decisions that happen around generation. Today, even a simple decision can require a generative model to process the input and produce an answer. Jev takes the input and returns a defined answer without generating output. That removes these decisions from the more expensive generation process.
TypeSafe reports that Jev was 193.6x faster and 444.6x cheaper on what it calls System One-shaped workflows, while noting that these vendor-run results are “on the higher end of real world gains.”
The important question for engineering teams is how many of these small decisions happen during an agent run. Count them. Then ask which could be handled as defined questions and which genuinely need a generative model. The more that can move out of the generative process, the greater the potential saving.
What Jev will not do
Jev’s limitations matter as much as its cost. It doesn’t write code, explanations, or drafts. Anything generative still belongs with a generative model. You also can’t simply ask it to “analyze this and decide the best course of action.” Complex judgments have to be broken into separate questions. Your software then combines the answers using rules and weights you control.
Context remains another constraint. With 32k available for state, a large repository won’t fit. Teams still have to decide what information should reach the model. And type safety shouldn’t be confused with correctness either. Jev always returns an answer that fits the options you provided. It therefore can’t hallucinate an answer outside that schema. But an allowed answer can still be wrong.
Forkast reported Jev at around 67.8% on TypeSafe’s internal benchmarks. Those benchmarks measure agreement with other frontier models, not independent ground truth. That distinction matters when a decision controls something consequential. Jev is also still in early access, with rate limits that can change without notice. As of September 2026, it is available through TypeSafe's API and listed on OpenRouter. TypeSafe hasn’t published the model weights.
For regulated organizations, that raises an immediate question before speed or cost are even considered: where can the model run?
Where this leaves your team
Jev’s interesting because it draws attention to a part of agentic delivery that’s easily overlooked. The generative step gets most of the attention. But an autonomous delivery system also depends on the decisions surrounding that step: whether to proceed, what information to use, what happened, and when to involve a person.
A System One model offers engineering teams another way to make those decisions. That doesn’t mean every judgment should move away from a frontier model. But teams can start identifying which decisions truly require generation and which could be handled by defined questions and confidence thresholds. If you already run coding agents, that’s the place to start: map the decisions around each generation step and determine what getting each one wrong would cost. That exercise will also help establish where your team sits on AI readiness and where stronger governance may be needed before autonomy expands.
Exadel is testing Jev through our AI engineering work and Exadel Colleague. We will publish our own test numbers when we have them.
Your AI Partner
Get notified when we publish our own test numbers.